FCR-PO: Learning Where to Retry in Language-Model Reasoning
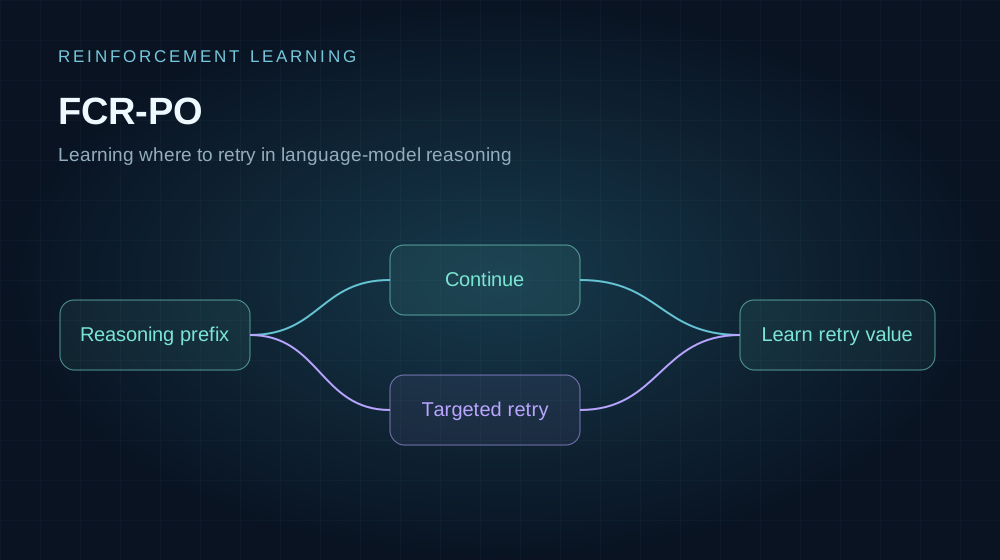
Learning the value of retrying reasoning steps by comparing targeted intervention with ordinary continuation. Exploration and credit assignment under a fixed training budget. Accepted at ACML 2026.
Jan–Jul 2026ACML 2026 · AcceptedFirst author / lead researcher
Reinforcement LearningLLM ReasoningCredit Assignment
Research overview
Learning the value of retrying reasoning steps by comparing targeted intervention with ordinary continuation. Exploration and credit assignment under a fixed training budget. Accepted at ACML 2026.
The focus is which decisions are worth learning from, not merely increasing retries or replay volume. Refer to the paper and latest CV for method details and experimental scope.